

Most Linux administrators assume their monitoring stack will catch trouble before users notice. In practice, the opposite is often true.
A service can be technically “up” — responding to pings, passing basic health checks — while quietly failing the people trying to use it. The gap between what monitoring tools report and what’s actually happening on the wire is where most modern outages hide.
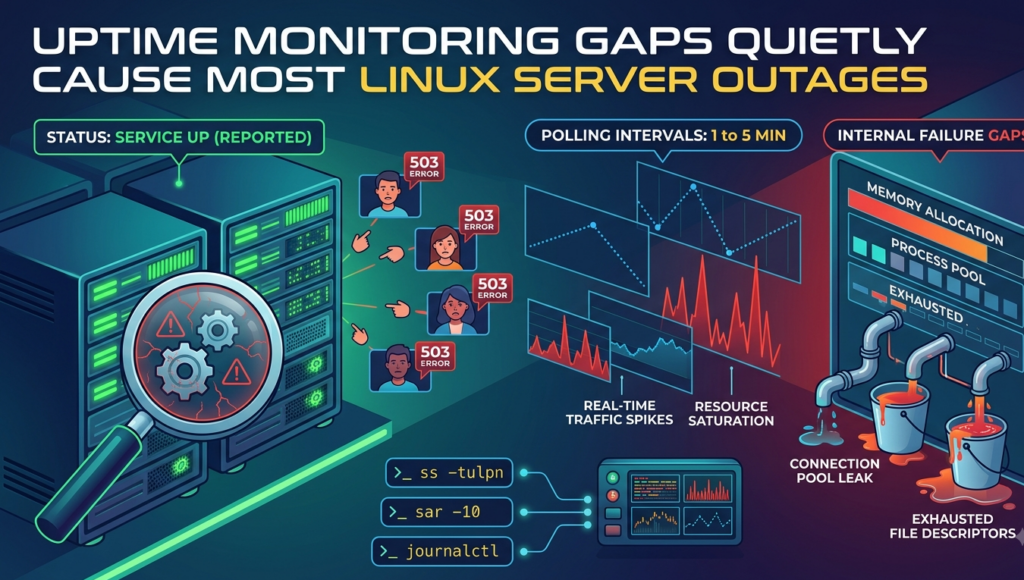
This isn’t a hardware problem. It’s a granularity problem. Default monitoring intervals, generic thresholds, and shallow health checks were built for a simpler era of single-server deployments.
Today’s distributed systems fail in subtler ways, and closing that visibility gap requires rethinking both tooling and cadence.
Default monitoring intervals miss critical failure windows
Standard monitoring setups check server health every one to five minutes. That cadence made sense when failures were binary — a server was either running or it wasn’t. Modern failures rarely work that way.
A misconfigured load balancer, a leaking connection pool, or a slow memory creep can degrade service for ten or fifteen minutes before crossing whatever threshold triggers an alert.
By the time the alert fires, users have already experienced the problem. The monitoring system technically worked; it just worked too slowly to matter.
Real-time traffic spikes expose blind monitoring gaps
Sudden traffic surges are where coarse monitoring fails most visibly. A sharp spike in concurrent connections can saturate a process pool or exhaust file descriptors in seconds, long before a five-minute polling interval catches the trend. By the time a dashboard updates, the damage is already done.
High-transaction environments illustrate this pressure well. Stock trading APIs process order bursts at market open that saturate connection pools faster than minute-level polling can detect.
Real-time multiplayer gaming servers absorb player session spikes during peak hours that exhaust file descriptors before a dashboard refresh cycle completes.
Online gambling platforms face the same pressure —crypto casinos listed by GamblingInsider depend on infrastructure that absorbs rapid load shifts without visible degradation and maintains sub-second response times under concurrent transaction bursts.
These environments demonstrate why granular, near-instant telemetry has become the baseline expectation rather than a luxury.
The broader outage data backs this up. Cloud service providers accounted for 27% of observed outages in 2024, up from just 17% the year before, according to a configuration-focused outage analysis.
Much of that increase traces back to configuration drift and partial failures — the exact category of problem that coarse-grained checks are structurally blind to.
Command-line tools for granular resource tracking
Closing the gap starts at the command line. Tools like ss -tulpn and lsof reveal socket-level behavior that generic uptime checks never touch, showing exactly which processes are holding connections open or leaking file descriptors.
Pairing these with sar and iostat at short polling intervals — 10 to 15 seconds rather than five minutes — surfaces resource saturation while it’s still building, not after it’s already caused visible slowdowns.
Log-based visibility matters just as much as resource metrics. Running journalctl -u servicename –since “10 minutes ago” alongside structured logging turns vague “service degraded” reports into specific, actionable error patterns.
Standardized approaches to collecting this telemetry, including documented Linux data collection methods, give teams a consistent baseline for building alerts on real signals instead of guesswork.
Building alert thresholds that match actual load patterns
Static thresholds — alert if CPU exceeds 90% — ignore the fact that normal load varies by hour, day, and deployment cycle.
Thresholds tuned to actual traffic patterns, rather than arbitrary round numbers, catch anomalies faster and generate far fewer false positives.
The financial case for this shift is measurable. Organizations with full-stack observability report median annual outage costs 59% lower than those relying on fragmented monitoring, according to New Relic’s 2023 Observability Forecast.
For Linux teams, that translates into a clear priority: invest in granularity now, or pay for blind spots later when they surface as downtime nobody saw coming.
